








使用 html_entity_decode() 函数可以去除字符串中的 html 实体。该函数会将像 <、& 这样的实体转换回对应的字符,默认行为是处理所有类型的实体并返回解码后的字符串。

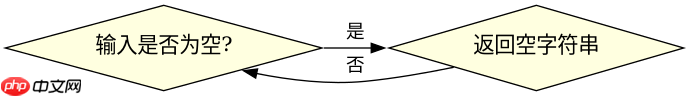
html_entity_decode() 遇到空输入会返回什么
当输入为空字符串时,html_entity_decode() 直接返回空字符串。它不会抛出异常或返回 null,而是保持原样输出,这符合 PHP 大多数字符串函数的常规行为。
$input = "";
$result = html_entity_decode($input);
var_dump($result); // string(0) ""
htmlspecialchars_decode() 与 html_entity_decode() 的区别是什么
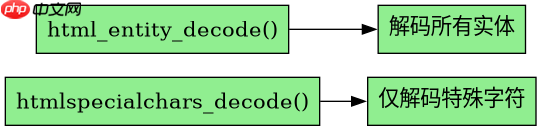
htmlspecialchars_decode() 仅解码由 htmlspecialchars() 编码的特殊字符,如 &、、<code>>、" 和 '。而 html_entity_decode() 范围更广,包括数字实体(如 ©)和命名实体(如 ©)。如果只需要还原基本的转义字符,前者更高效且安全;如果需要还原所有实体,则用后者。

立即学习“PHP免费学习笔记(深入)”;
$input = "<b>Hello</b> © 2023"; $decoded1 = htmlspecialchars_decode($input); $decoded2 = html_entity_decode($input); echo $decoded1; // <b>Hello</b> © 2023 echo $decoded2; // <b>Hello</b> © 2023
如何处理带有特定编码的 HTML 实体?
可以通过设置 html_entity_decode() 的第二个参数 $flags 和第三个参数 $encoding 来控制解码行为。例如,指定 UTF-8 编码可以确保中文实体被正确解码。默认编码通常是 UTF-8,但在某些旧系统或配置中可能需要显式指定以避免乱码。
$input = "中文";
$decoded = html_entity_decode($input, ENT_QUOTES | ENT_HTML5, 'UTF-8');
echo $decoded; // 中文


















